AnyGroundBench

A Multi-Domain Adaptation Benchmark for Video Grounding in VLMs

Rintaro Otsubo*1,2 Ryo Fujii*1,2 Reina Ishikawa1,2 Taiki Kanaya1,2 Kanta Sawafuji1,2 Hiroki Kajita1,3 Shigeki Sakai1,3 Hideo Saito1,2 Ryo Hachiuma4
1Keio University 2Keio AI Research Center 3Keio University School of Medicine 4NVIDIA

* Equal contribution

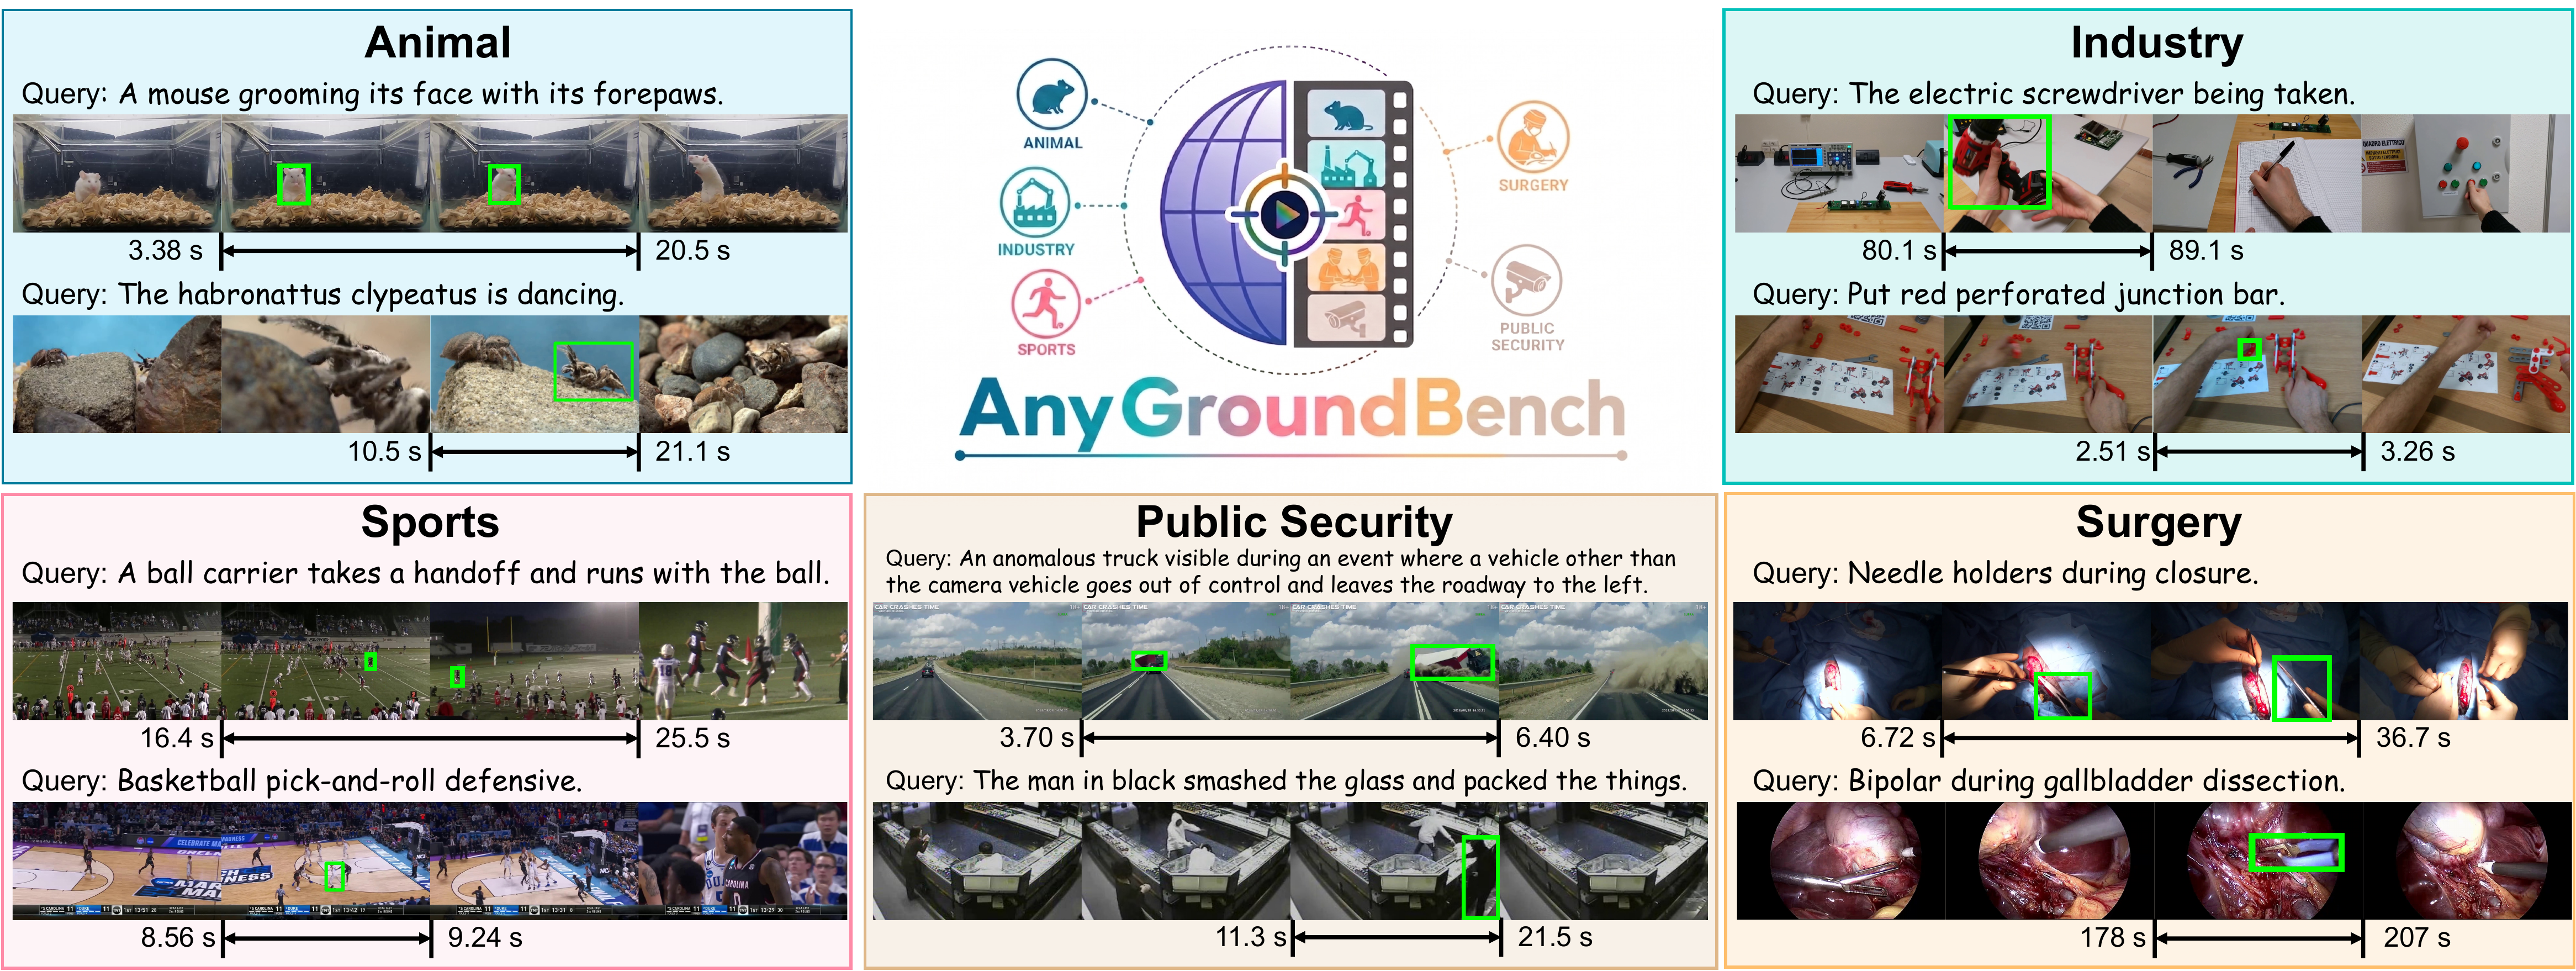
AnyGroundBench teaser
AnyGroundBench evaluates spatio-temporal video grounding across specialized domains including animal, industry, sports, surgery, and public security.

Abstract

Vision-Language Models (VLMs) have shown strong performance in Spatio-Temporal Video Grounding (STVG), yet they are still evaluated mostly in a zero-shot manner on general-purpose benchmarks of everyday scenes. This creates a critical disconnect from real-world applications in specialized domains, where models inevitably encounter rare visual or textual concepts. Since exhaustive pre-training across infinite data distributions is infeasible, the ability to adapt to novel domains with limited data is essential.

To bridge this gap, we introduce AnyGroundBench, a domain-adaptation benchmark designed to shift the STVG evaluation paradigm from static zero-shot testing to rigorous domain adaptation. Targeting five specialized domains (animal, industry, sports, surgery, and public security), AnyGroundBench pairs newly captured, expert-annotated videos with established datasets, unifying them through dense, high-fidelity spatio-temporal annotations. Crucially, the benchmark provides dedicated limited training subsets, enabling systematic evaluation of domain adaptability under limited training data.

We benchmark 23 state-of-the-art VLMs in the zero-shot setting and further evaluate five adaptation strategies, spanning training-free and fine-tuning-based approaches, on representative models, assessing their zero-shot generalization and adaptation capacity. Our results show that current VLMs remain far from practical performance in the zero-shot setting, that training-free adaptation produces highly variable effects depending on the model and domain, and that fine-tuning-based adaptation, though more effective, still falls short of real-world requirements, with gains varying markedly across domains. These findings expose fundamental limitations in current VLMs' spatio-temporal reasoning, pointing to concrete directions for future research.

Zero-shot Results

Each cell reports STVG / TVG / SVG. STVG uses vIoU@0.3, TVG uses tIoU@0.3, and SVG uses sIoU@0.3. Bold and underlined values denote the best and second-best results, respectively.

Models Animal Industry Sports Surgery Public Security
Proprietary VLMs
GPT-4o0.00 / 16.6 / 7.642.96 / 8.88 / 14.80.61 / 17.2 / 0.000.00 / 13.4 / 0.000.80 / 56.0 / 4.40
GPT-5.13.18 / 19.7 / 55.45.33 / 9.47 / 28.40.00 / 25.8 / 1.841.39 / 22.7 / 0.674.80 / 61.2 / 35.6
GPT-5.46.37 / 21.7 / 65.64.73 / 12.4 / 33.10.61 / 32.5 / 5.521.39 / 38.9 / 2.682.00 / 68.0 / 53.6
GPT-5.6-Sol15.3 / 25.5 / 92.410.7 / 24.3 / 47.96.13 / 44.2 / 45.47.87 / 32.4 / 27.520.8 / 67.2 / 88.4
GPT-5.6-Terra13.4 / 22.3 / 86.06.51 / 17.2 / 43.84.91 / 31.9 / 31.34.17 / 32.4 / 10.118.4 / 56.8 / 83.2
GPT-6-Astra19.1 / 36.3 / 97.57.10 / 24.9 / 53.84.91 / 46.0 / 58.325.9 / 47.7 / 61.718.8 / 76.0 / 93.6
Gemini-2.5-Flash2.55 / 26.1 / 15.30.59 / 21.3 / 4.731.84 / 31.9 / 3.680.00 / 22.7 / 0.670.40 / 51.2 / 2.00
Gemini-2.5-Pro8.28 / 36.9 / 20.41.18 / 39.6 / 17.20.61 / 37.4 / 8.591.39 / 31.5 / 3.364.00 / 65.9 / 22.8
Gemini-3-Flash14.6 / 36.3 / 52.25.92 / 30.8 / 20.12.45 / 29.4 / 2.450.93 / 38.0 / 13.411.2 / 66.8 / 45.6
Gemini-3.1-Pro16.6 / 37.6 / 70.77.69 / 21.9 / 41.41.23 / 26.4 / 16.64.17 / 32.9 / 34.222.8 / 69.5 / 52.0
Gemini-3.5-Flash16.6 / 41.4 / 66.95.92 / 19.5 / 47.34.91 / 30.1 / 15.34.17 / 30.1 / 29.522.4 / 61.6 / 52.0
Gemini-3.8-Flash17.2 / 38.9 / 66.27.69 / 20.1 / 37.34.29 / 36.2 / 12.99.26 / 35.6 / 41.628.4 / 75.2 / 56.0
Open-source Specialized VLMs
LLaVA-ST12.1 / 19.7 / 53.50.00 / 9.47 / 12.40.79 / 8.59 / 3.680.00 / 12.0 / 0.000.80 / 35.6 / 13.2
Open-source General-Purpose VLMs
Qwen3-VL-4B5.73 / 25.5 / 42.00.00 / 4.14 / 13.00.00 / 8.59 / 0.000.00 / 13.4 / 0.000.40 / 39.2 / 0.00
Qwen3-VL-8B3.82 / 19.7 / 17.80.00 / 10.7 / 7.690.00 / 11.7 / 0.000.00 / 15.7 / 0.000.80 / 46.0 / 3.60
Qwen3.5-4B2.55 / 30.6 / 13.40.00 / 14.8 / 7.690.00 / 12.9 / 0.000.00 / 28.2 / 1.340.40 / 49.2 / 2.00
Qwen3.5-9B4.46 / 35.0 / 20.40.59 / 17.2 / 12.40.61 / 14.7 / 0.000.00 / 28.2 / 1.340.40 / 50.4 / 4.80
Qwen3.8-27B12.7 / 26.1 / 12.75.33 / 18.3 / 28.40.00 / 11.0 / 1.230.00 / 35.2 / 10.113.6 / 56.4 / 2.80
Eagle2.5-8B0.00 / 24.8 / 1.270.00 / 7.69 / 2.370.00 / 7.98 / 0.000.00 / 15.3 / 0.000.00 / 47.6 / 0.40
InternVL3-8B0.64 / 15.3 / 3.820.00 / 5.92 / 1.180.00 / 6.79 / 0.000.00 / 10.6 / 0.000.00 / 4.40 / 0.80
InternVL3-14B0.64 / 17.8 / 7.640.00 / 5.33 / 1.180.00 / 7.36 / 0.000.00 / 10.6 / 0.000.00 / 13.2 / 0.00
InternVL3.5-8B0.00 / 11.5 / 0.000.00 / 2.96 / 1.180.00 / 6.13 / 0.000.00 / 7.41 / 0.000.00 / 3.60 / 0.00
Gemma4-12B5.10 / 27.4 / 3.824.14 / 11.2 / 18.30.00 / 9.20 / 0.002.31 / 25.0 / 2.011.60 / 43.2 / 0.00

Qualitative Examples

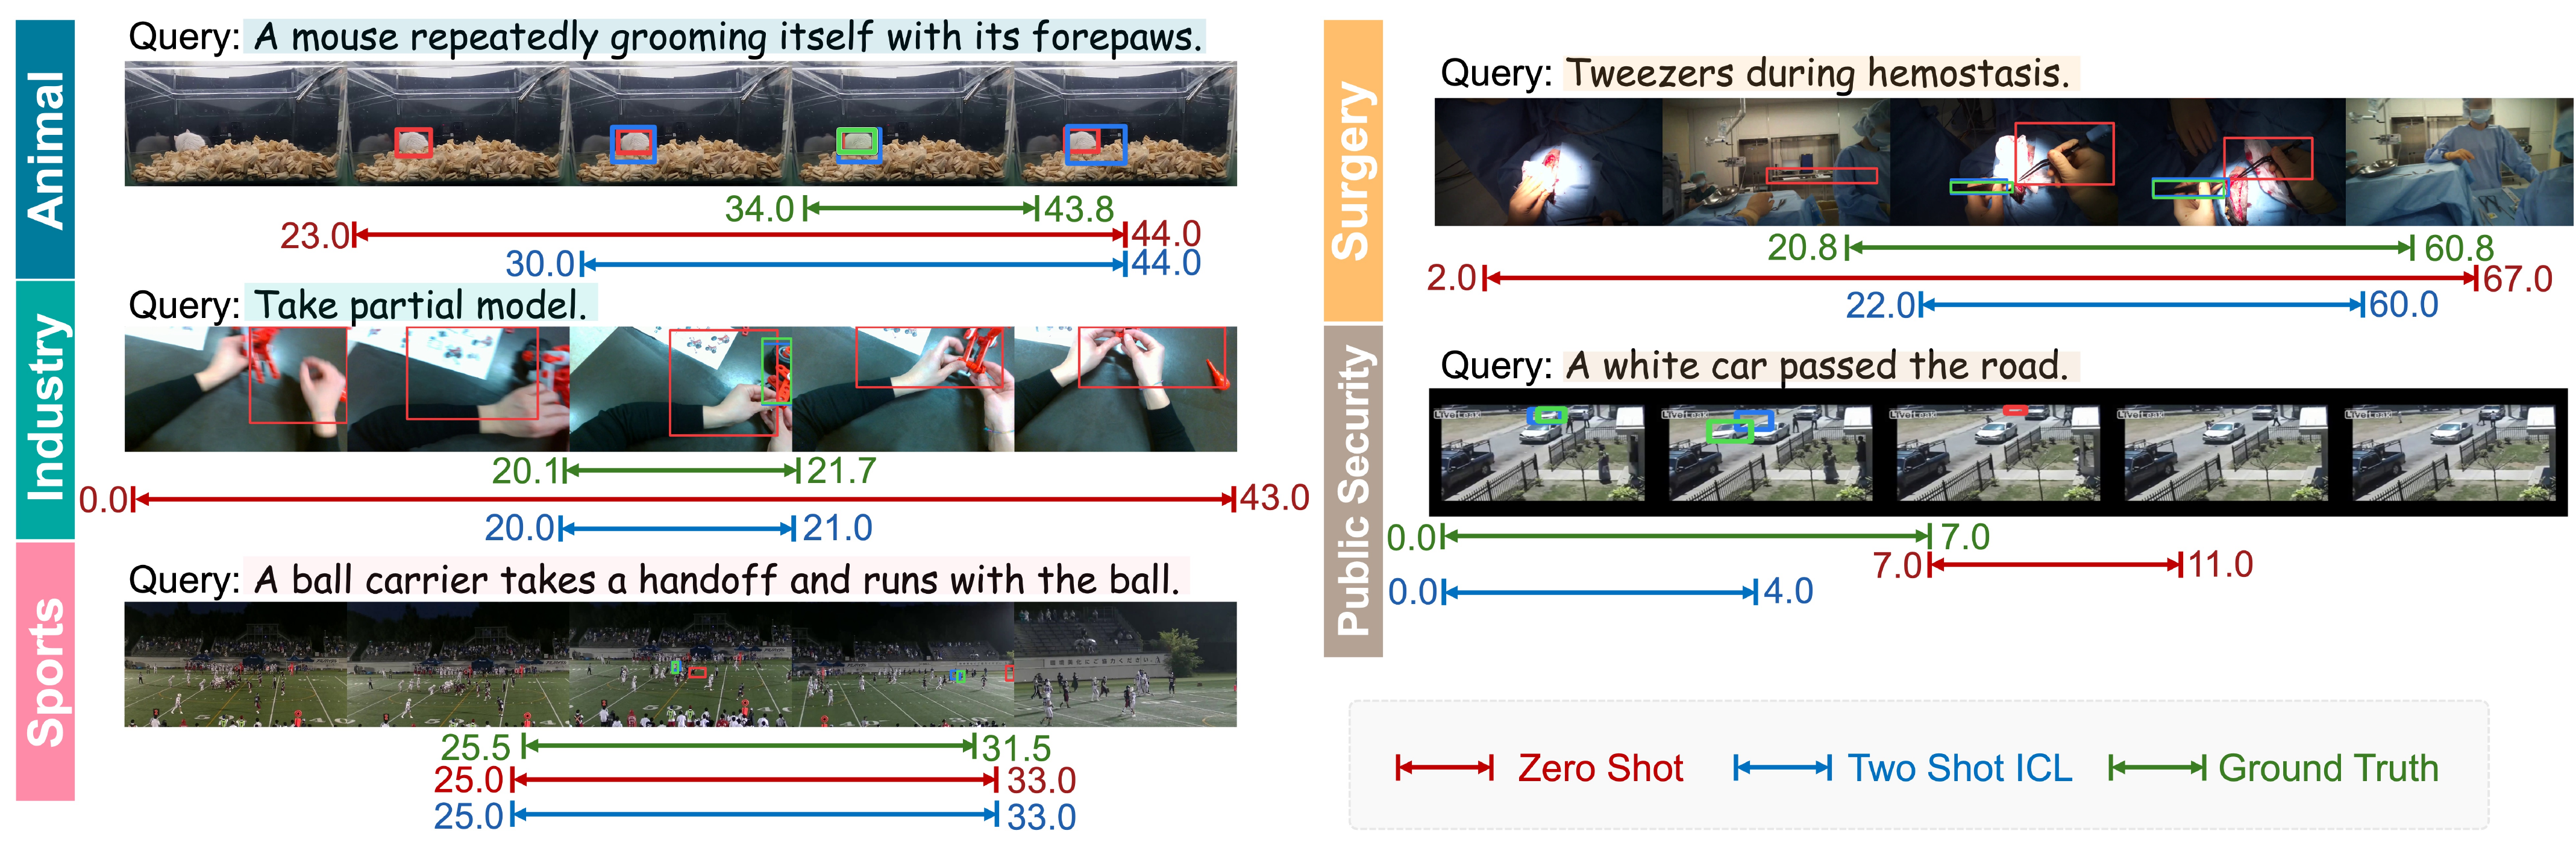
Qualitative examples
Qualitative visualization of specialized-domain spatio-temporal grounding examples.